Education
Vision models for the unglamorous, high-volume work: reading forms, scoring answer sheets, checking images, and flagging what a person needs to look at.
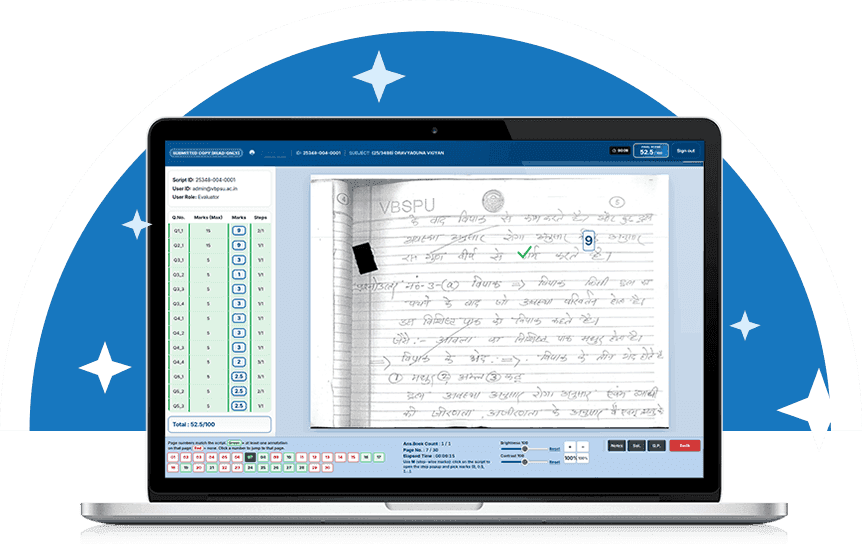
Our computer vision practice grew out of examination processing. University OMR and on-screen marking platforms we built read, validate, and score sheets in volumes that make manual handling impossible, which forced us to care about the things that decide whether a vision system survives contact with reality: poor scans, skewed pages, smudged marks, and the audit trail that has to justify every score.
The same discipline transfers to any high-volume visual task. We build OCR and handwriting recognition for forms and registers, classification and defect detection for images, and video analytics for counting and monitoring. Every model ships with a confidence threshold and a human review queue, because the right answer to a low-confidence prediction is a person, not a guess.
Common pain points organizations face before engaging Quaere.
Staff retype forms, registers, and submissions into a system by hand, which is slow, expensive, and introduces errors nobody can trace back to a source.
Seasonal peaks such as examinations, admissions, or claims arrive faster than the people available to process them, and the backlog becomes the deadline.
A result that affects a student, patient, or claimant has to be explainable and reversible, and an unaudited automated score is not something an institution can stand behind.
Models trained on clean samples fail on the real intake: faint photocopies, rotated pages, mobile photographs, and forms filled in outside the boxes.
Targeted solutions we design and deliver for your organization.
OMR scanning, field extraction, and validation at examination-board volumes, with automated checks for duplicates, blanks, and multiple marks.
Every prediction carries a confidence score, and anything below the agreed line routes to a human reviewer instead of being accepted silently.
The original image, the extracted value, the model version, and any human correction are all retained, so a disputed result can be reconstructed months later.
We train and test on your actual scans, including the bad ones, and report accuracy per field and per document type rather than as a single headline number.
What your organization gains when AI is built for real users in healthcare, education, government, and private sector.
From deep learning models and chatbots to full platforms like HealthRely and university OSM, we cover the full build.
How we take projects from planning to live systems, the same way we delivered Nyay Marg AI, HealthRely, and university OSM platforms.
01
Sample and baseline
Collect a representative set of your real images, including the poor ones, and measure how the current manual process performs on them.
02
Annotate and train
Label the fields and classes that matter, train candidate models, and measure accuracy per field rather than as a single average.
03
Pipeline and review
Wrap the model in the surrounding system: intake, preprocessing, validation rules, confidence thresholds, and the human review queue.
04
Deploy and scale
Run it on the real volume with the throughput, retry handling, and monitoring that a processing deadline requires.
05
Retrain and extend
Feed corrections from the review queue back into training, and add new formats as intake changes year to year.
The tools and platforms behind our live systems for UPSLSA, Chandan Healthcare, universities, and enterprise clients.




Healthcare, legal services, education, government, and private sector, where we have delivered production systems.
Education
Government & Public Sector
Healthcare
Banking & Finance
Manufacturing
Logistics
Explore how we serve your sector on our Industries page.
Why government bodies, universities, hospitals, and private companies choose Quaere for AI and software they can rely on daily.
Built and run OMR and on-screen marking platforms at university examination scale
Accuracy reported per field and document type, not as one convenient average
Human review built in from the start, because institutional decisions need it
Full audit trail from original scan to final value, retained for dispute handling
ISO 9001:2015 certified quality management and CMMI Level 3 processes
Common questions from teams planning AI chatbots, healthcare apps, university platforms, or ML projects.
Send us a representative sample, including the bad scans, and we will come back with measured accuracy rather than an estimate.
No commitment required • Response within 24 hours
Tell us what you need and the team will come back to you within one to two working days. No obligation, and no sales sequence.
Other services that often work together, for example chatbots plus knowledge systems, or SaaS plus integrations.
Intelligent Document Processing
Automated extraction from forms, invoices, certificates, and scanned records, with validation rules, human review, and an audit trail on every field.
AI/ML Solutions
Deep learning, predictive analytics, and production ML for universities, healthcare, government, and enterprise.
Workflow Automation
Intelligent process automation that reduces manual work and accelerates decision-making.